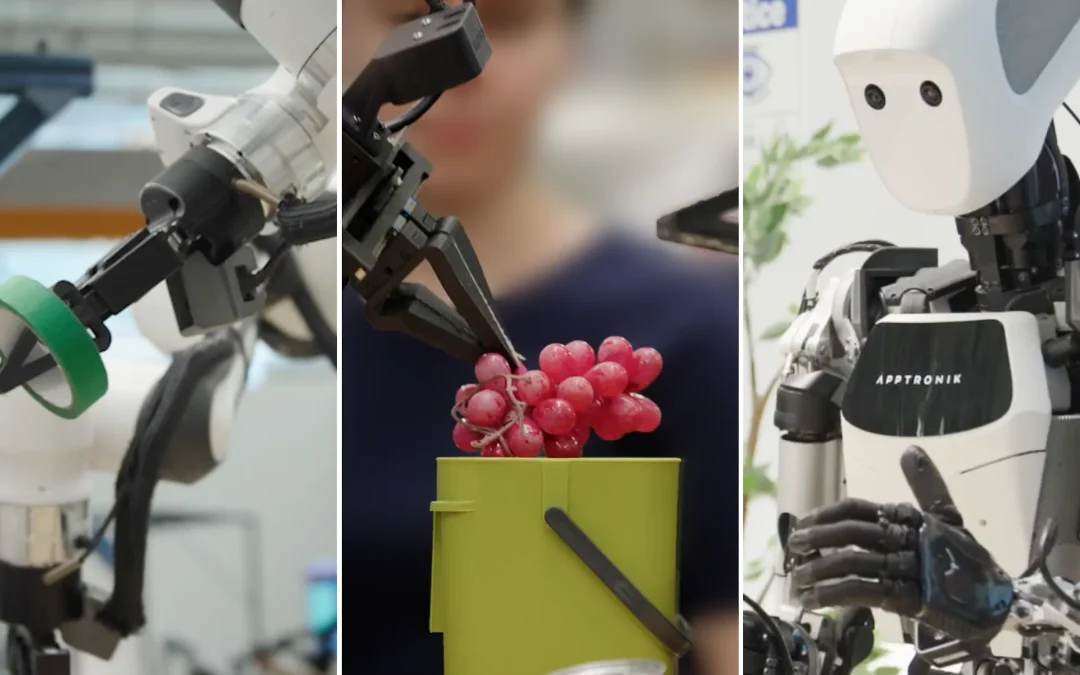
(Photo: Google)
London, UK — September 25, 2025
Google DeepMind today announced the release of its latest robotics‑oriented AI models, Gemini Robotics 1.5 and Gemini Robotics‑ER 1.5, aimed at enabling robots to understand, plan, and carry out complex physical tasks with more autonomy and intelligence.
The new models build on DeepMind’s foundational Gemini Robotics work first introduced in March 2025, with a dual‑model architecture that separates action execution from high‑level reasoning. Gemini Robotics 1.5 — a vision‑language‑action (VLA) model — transforms visual input and natural‑language instructions into motor commands that help robots perform multi‑step tasks. Meanwhile, Gemini Robotics‑ER 1.5 — an embodied reasoning (ER) model — provides strategic planning and logical decision‑making before actions are taken.
By enabling robots to interpret their surroundings, generate detailed task plans, and act on them, DeepMind’s models represent a significant advance toward robots capable of real‑world reasoning rather than simply executing pre‑programmed motions. These updates make it possible for developers to build robots with a deeper understanding of contextual information and stepwise task execution.
DeepMind notes that Gemini Robotics‑ER 1.5 is now available to developers through the Gemini API in Google AI Studio, while Gemini Robotics 1.5 is being offered to select partners for initial integration and testing.
Although this does not mean humanoid robots will be fully autonomous helpers in homes or businesses overnight, the advancement points to concrete progress in embodied AI — where intelligent systems can plan, reason, and act with greater sophistication in physical environments, accelerating efforts across robotics research and industrial applications.